AI Extraction From Any Document Format
Any document. Structured data. Seconds.
Drop any PDF — invoice, PO, contract, receipt — and get structured, queryable data extracted by AI. No templates to configure. No training period. Works on day one.
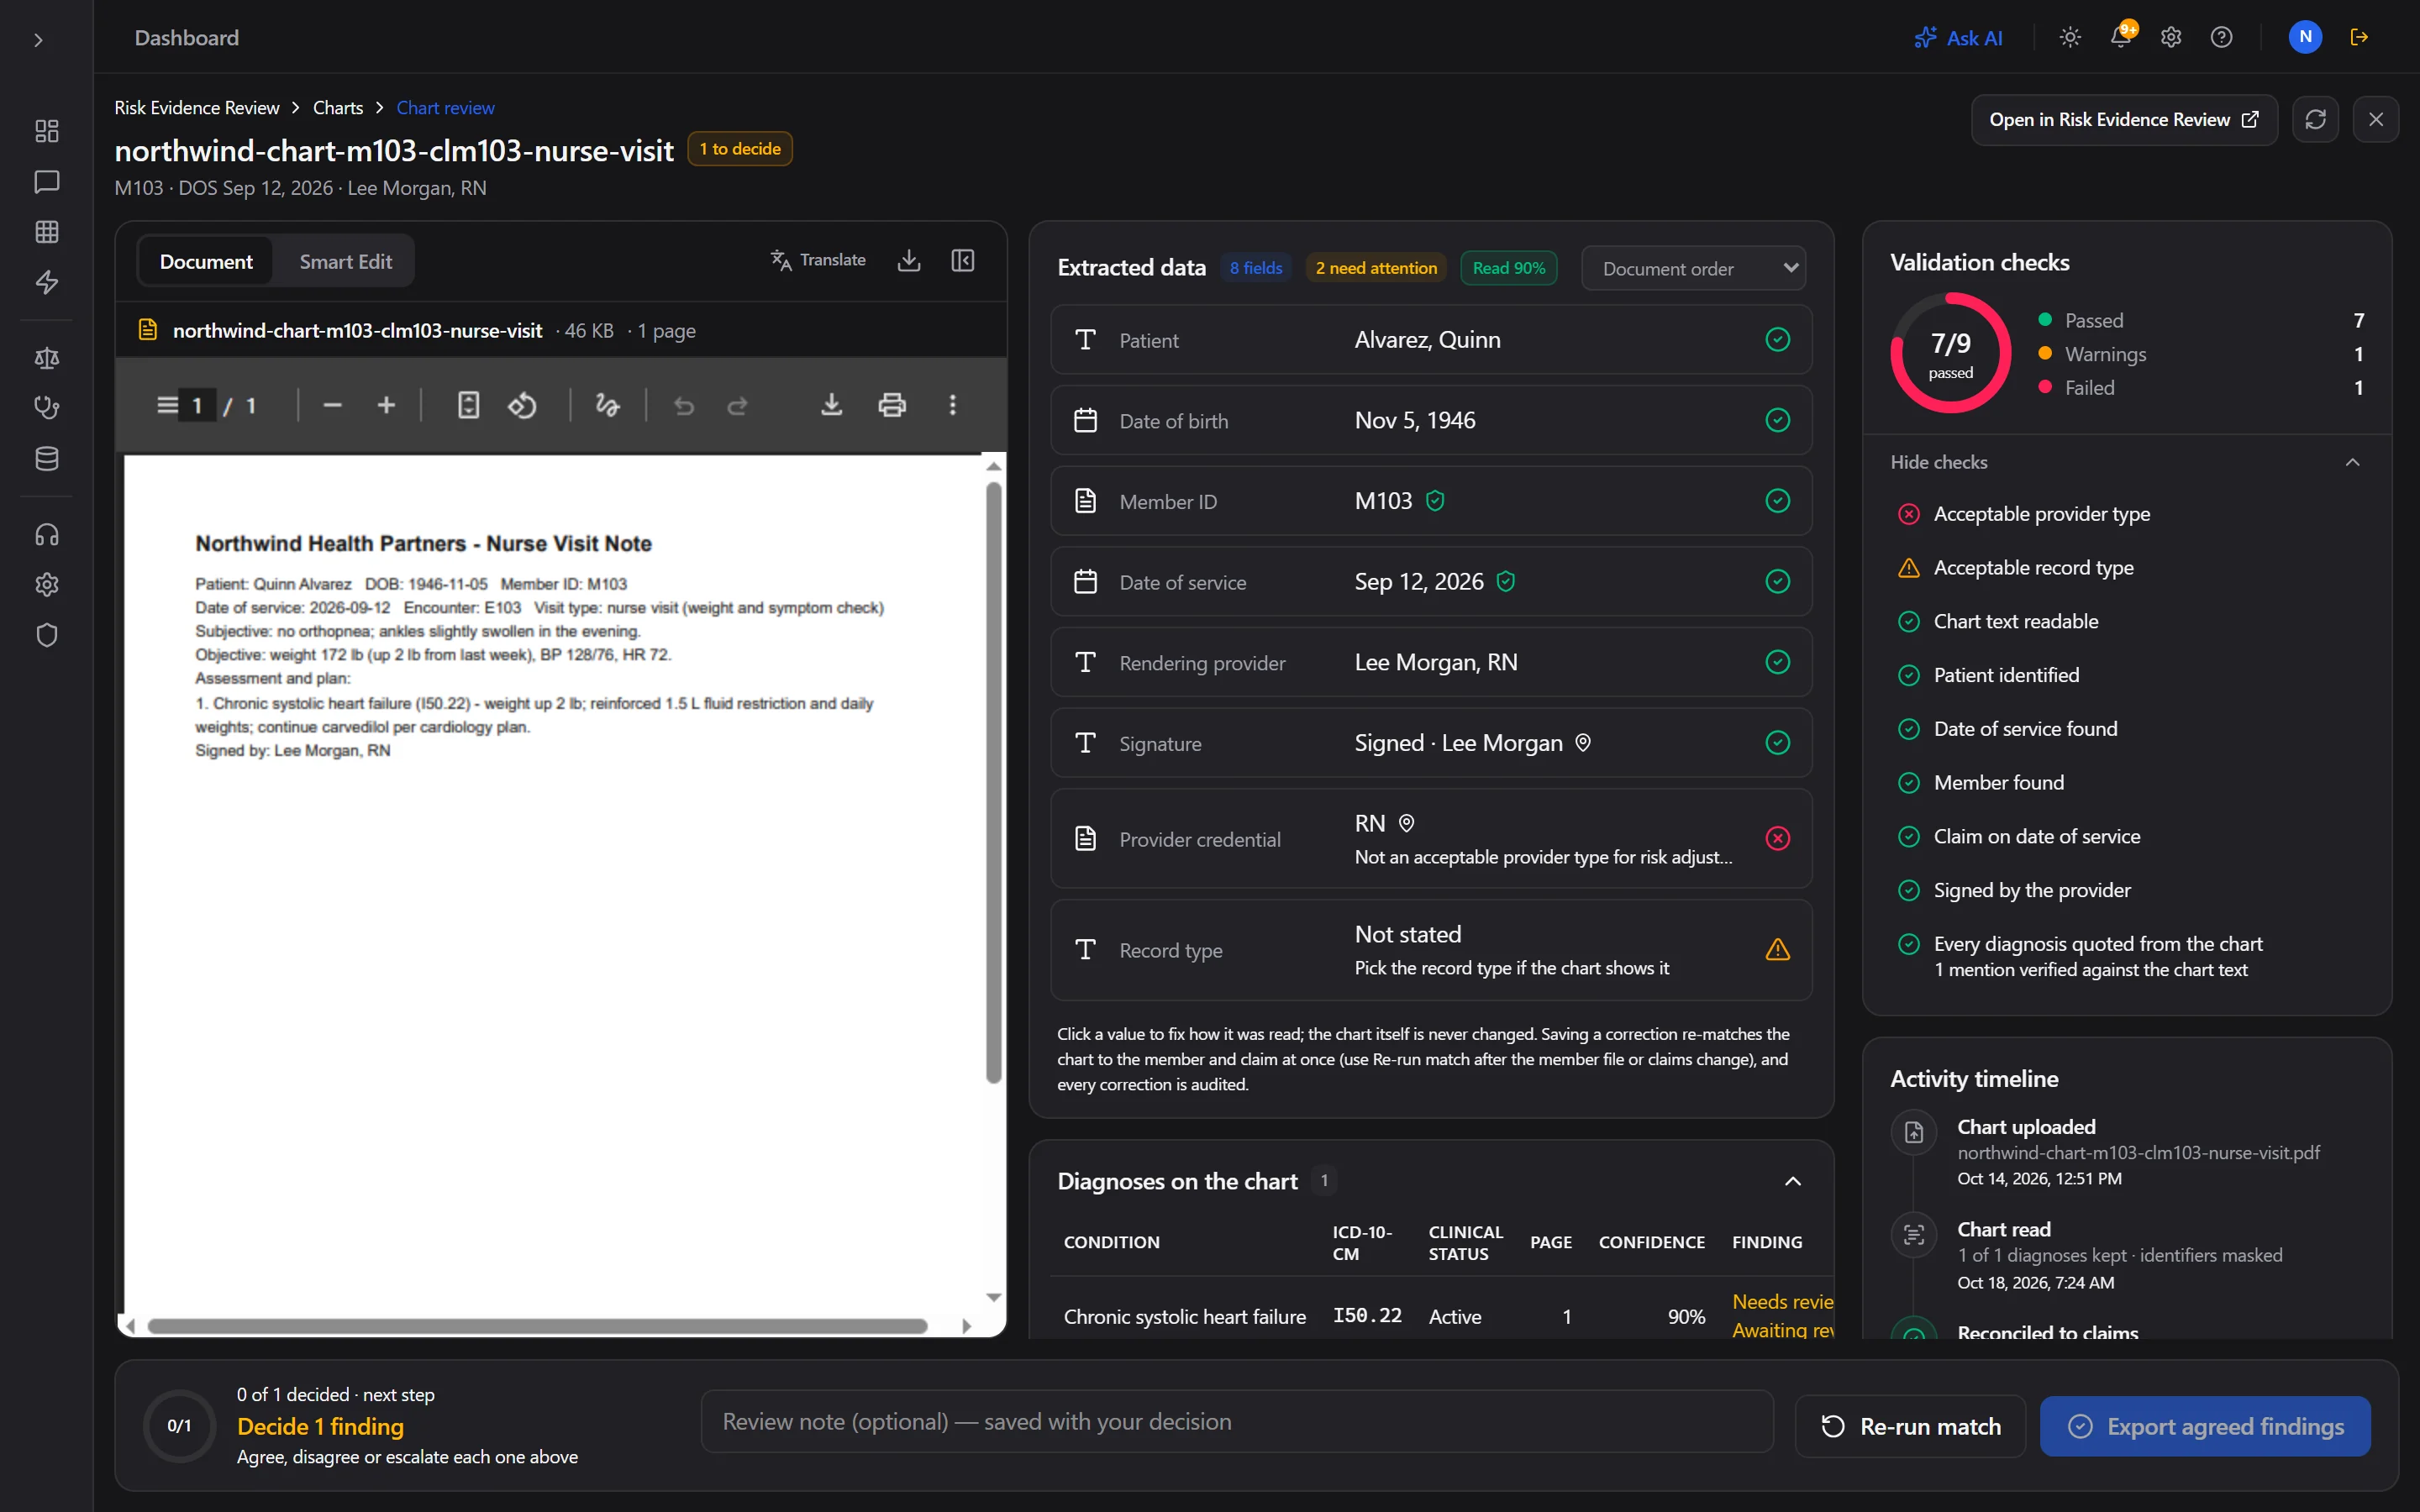
One review screen for every document type. Here, a clinical chart: the page beside each field read, documentation checks and audited corrections. Live product, synthetic data.
90+
Languages
Per field
Confidence & Source Shown
Audited
Every Correction
Zero
Templates Needed
How it works
Upload any document
PDF, scanned image, or digital document. Single file or bulk upload. Connect SharePoint/email for automatic ingestion.
AI extraction
Multi-model pipeline: OCR for scans, layout analysis for structure, LLM for semantic understanding. Extracts headers, line items, totals, dates, parties.
Validation & human review
Cross-checks extracted totals against line-item sums and enriches with vendor master data. A review screen puts the source beside every field, with its confidence, so a person can confirm or correct it.
Route to workflow
Extracted documents flow into matching, approval, or analytics pipelines automatically based on document type.
Capabilities
Zero-template extraction
No vendor-specific templates to maintain. AI adapts to any invoice format — new vendors work immediately without configuration.
Multi-language OCR
90+ languages supported natively. Process global invoices from international vendors without translation steps.
Line-item extraction
Not just headers — extracts every line item with description, quantity, unit price, tax, and extended amount.
Document translation
In-place translation preserves document layout. Read and process foreign-language documents without external tools.
Automatic ingestion
Connect SharePoint folders, email inboxes, or cloud storage. New documents are automatically extracted and routed.
Duplicate prevention
Content fingerprinting detects duplicate uploads during ingestion — before extraction runs, saving compute and preventing confusion.
Review and correction
One review screen for invoices and clinical charts: the source beside every field, validation checks and an activity timeline. Corrections are kept beside the original reading and audited, and the document re-matches at once.
Every AI read on the record
Each clinical chart read records the model, the time and the exact output, and every invoice correction and decision records who made it, when and why.
Frequently asked questions
Do I need to configure templates?
No. The AI adapts to any document layout without templates. This is the key difference from legacy OCR tools.
What about handwritten or low-quality scans?
Multi-model pipeline handles degraded scans. Confidence scores flag documents that may need human verification.
Can people correct what the AI extracted?
Yes. On the review screen, click a value to correct it. The source document is never edited: the correction is validated, kept beside the AI's original reading and audited, and anything that depends on it, such as the PO match or the chart's member match, is re-run at once.
How many documents can I process per day?
No hard limits. The pipeline scales with your volume — from 10 to 50,000+ documents daily.
See what we find before you commit.
Read-only connection. We review a sample of your invoices, agreements and supplier spend, then hand back a findings report with specific figures. If there is nothing to recover, there is nothing to pay.